Fine-tuning LLMs on OpenFOAM (computational fluid dynamics) tutorials and documentation, so models can generate and troubleshoot CFD simulation setups. Built in Prof. Shaowu Pan's Computational Scientific Machine Learning Lab at RPI. See the Pan & FoamGPT work experience entry.
Made a real, substantial commit rewriting the fine-tuning pipeline, environment config, and README (Sept 2025). This project resulted in a published NeurIPS 2025 ML4PS workshop paper by the lab; not an authorship credit for this contribution.
PythonHugging Face TransformersPEFT / LoRAbitsandbytesTRLFAISSconda
POEM: Psychometrics Ontology of Entities and MeasuresLab contribution
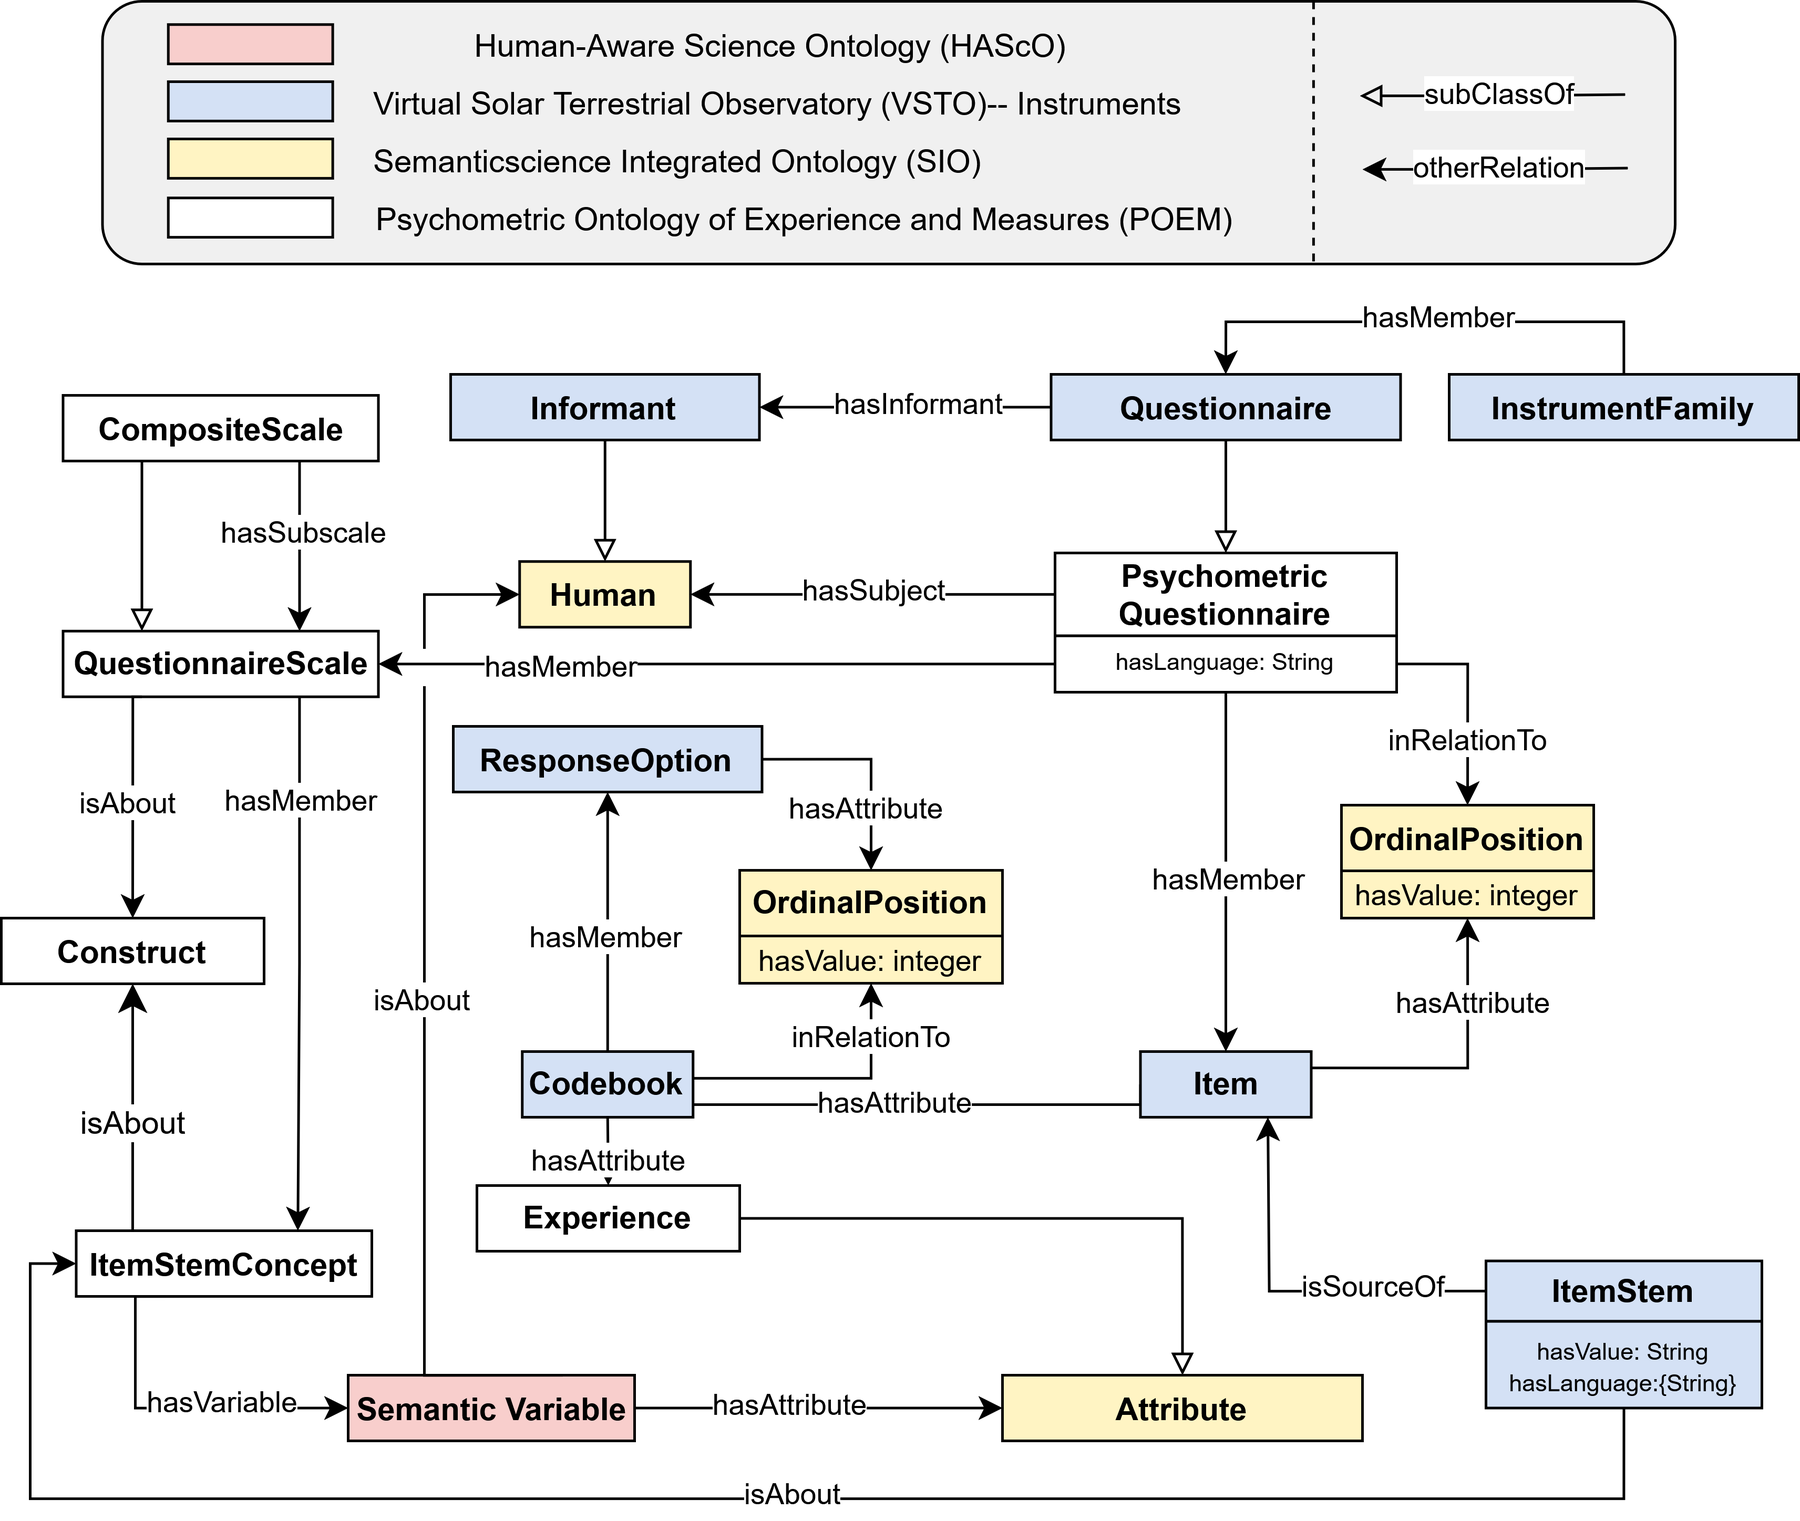
An RPI Tetherless World Constellation ontology structuring relationships between psychological/clinical assessment instruments (e.g. RCADS, PHQ-9) and their components, for interoperability across mental-healthcare data. Directly related to the AI Systems Engineer role above.
Authored and merged the embedding/retrieval pipeline (RDF/SPARQL over an in-memory graph, Dockerized Apache Jena Fuseki + TDB2 triple store, an OpenAI-compatible client against a self-hosted embedding model), then expanded the evaluation harness from 12 to 50 queries and fixed a retrieval-quality bug in the unscoped search path.
POEM's ontology class diagram: the schema the embedding/retrieval pipeline above is built on.
Wanted one place where people could get a complete view of who I am — professionally and personally — rather than a resume that only ever covers half of it. Built the whole site myself: every page, the design system, and an “Ask about Armaan” AI chatbot on every page.
The chatbot is a small RAG (retrieval-augmented generation) pipeline I wrote from scratch: a build script parses the site's own HTML into a knowledge graph and embeds each chunk with Voyage AI, then a Lambda function embeds each visitor's question, retrieves the most relevant chunks by cosine similarity, and hands them to Claude to write an answer grounded only in what's actually on the site — nothing invented. The topic pill under each answer is picked by a small multi-signal consensus (chunk-level embedding similarity, page-level embedding similarity, and a strict literal-keyword check) rather than raw cosine similarity alone, so it lands on the one page that's actually relevant instead of whatever happened to ride along in a single metric's top results. The goal was to let visitors ask a direct question and get pointed straight to the right page instead of digging through the nav themselves.
No GitHub repo for this one — all the code (site, chatbot build script, and Lambda handler) is written locally and deployed by hand: static files uploaded straight to S3, and the Lambda code zipped and uploaded through the AWS Console, with no CI/CD pipeline.
A Texas Hold'em odds calculator: give it hole and community cards and it estimates each player's win probability via Monte Carlo simulation, recalculating live as cards are dealt. Ships an interactive CLI and a live-camera mode. A fine-tuned YOLOv8 model reads cards off a physical table through a webcam, feeding a PySide6 GUI with an animated table, per-seat calibration, and a REINFORCE-trained RL agent that advises fold/call/raise.
The card-face assets from the repo, used for both UI rendering and YOLOv8 detector training/output.
Jarvis: Computer-Vision Home SecurityShowcase (source private)
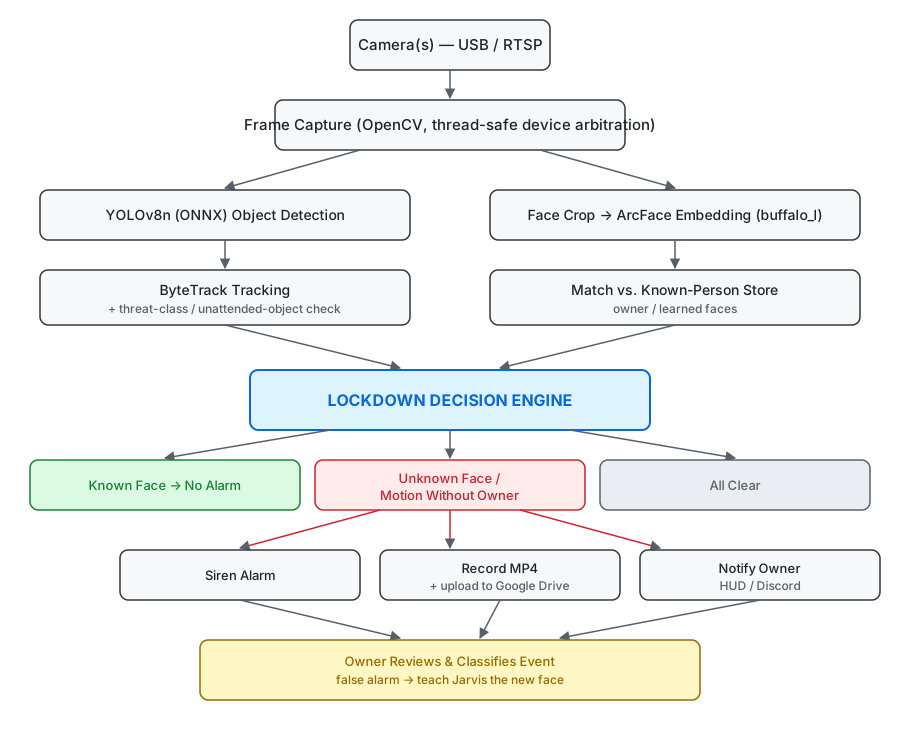
One module of a larger local-first, voice-driven, multi-agent personal assistant: recognizes known faces (InsightFace ArcFace), detects and tracks objects (YOLOv8n + ByteTrack), and runs an always-on lockdown mode that alarms, records, and uploads footage on an unrecognized face or motion-without-owner. The broader assistant routes requests through a local model (Ollama/vLLM) before falling back to Claude, orchestrates ~40 tool integrations across sub-agents, and talks/listens fully offline via Whisper and Piper.
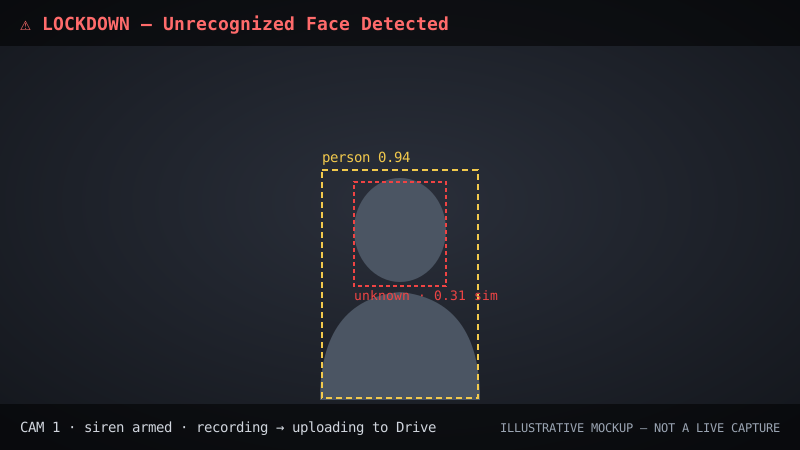
System architecture, from the project README.Illustrative mockup of the lockdown alert UI (not a live capture).
Source and camera/face data are private (real home cameras and family members' faces, live OAuth tokens). This showcase repo has the architecture and README only, so the tech stack here is self-reported, not independently code-verified.
A Next.js app that uses AI to help compose email, with Google/Outlook integration and multi-user support. Built with Prisma over SQLite in development (Postgres via Neon in production), NextAuth with Google and Azure OAuth, and the Anthropic API for generation; deploys to Railway.
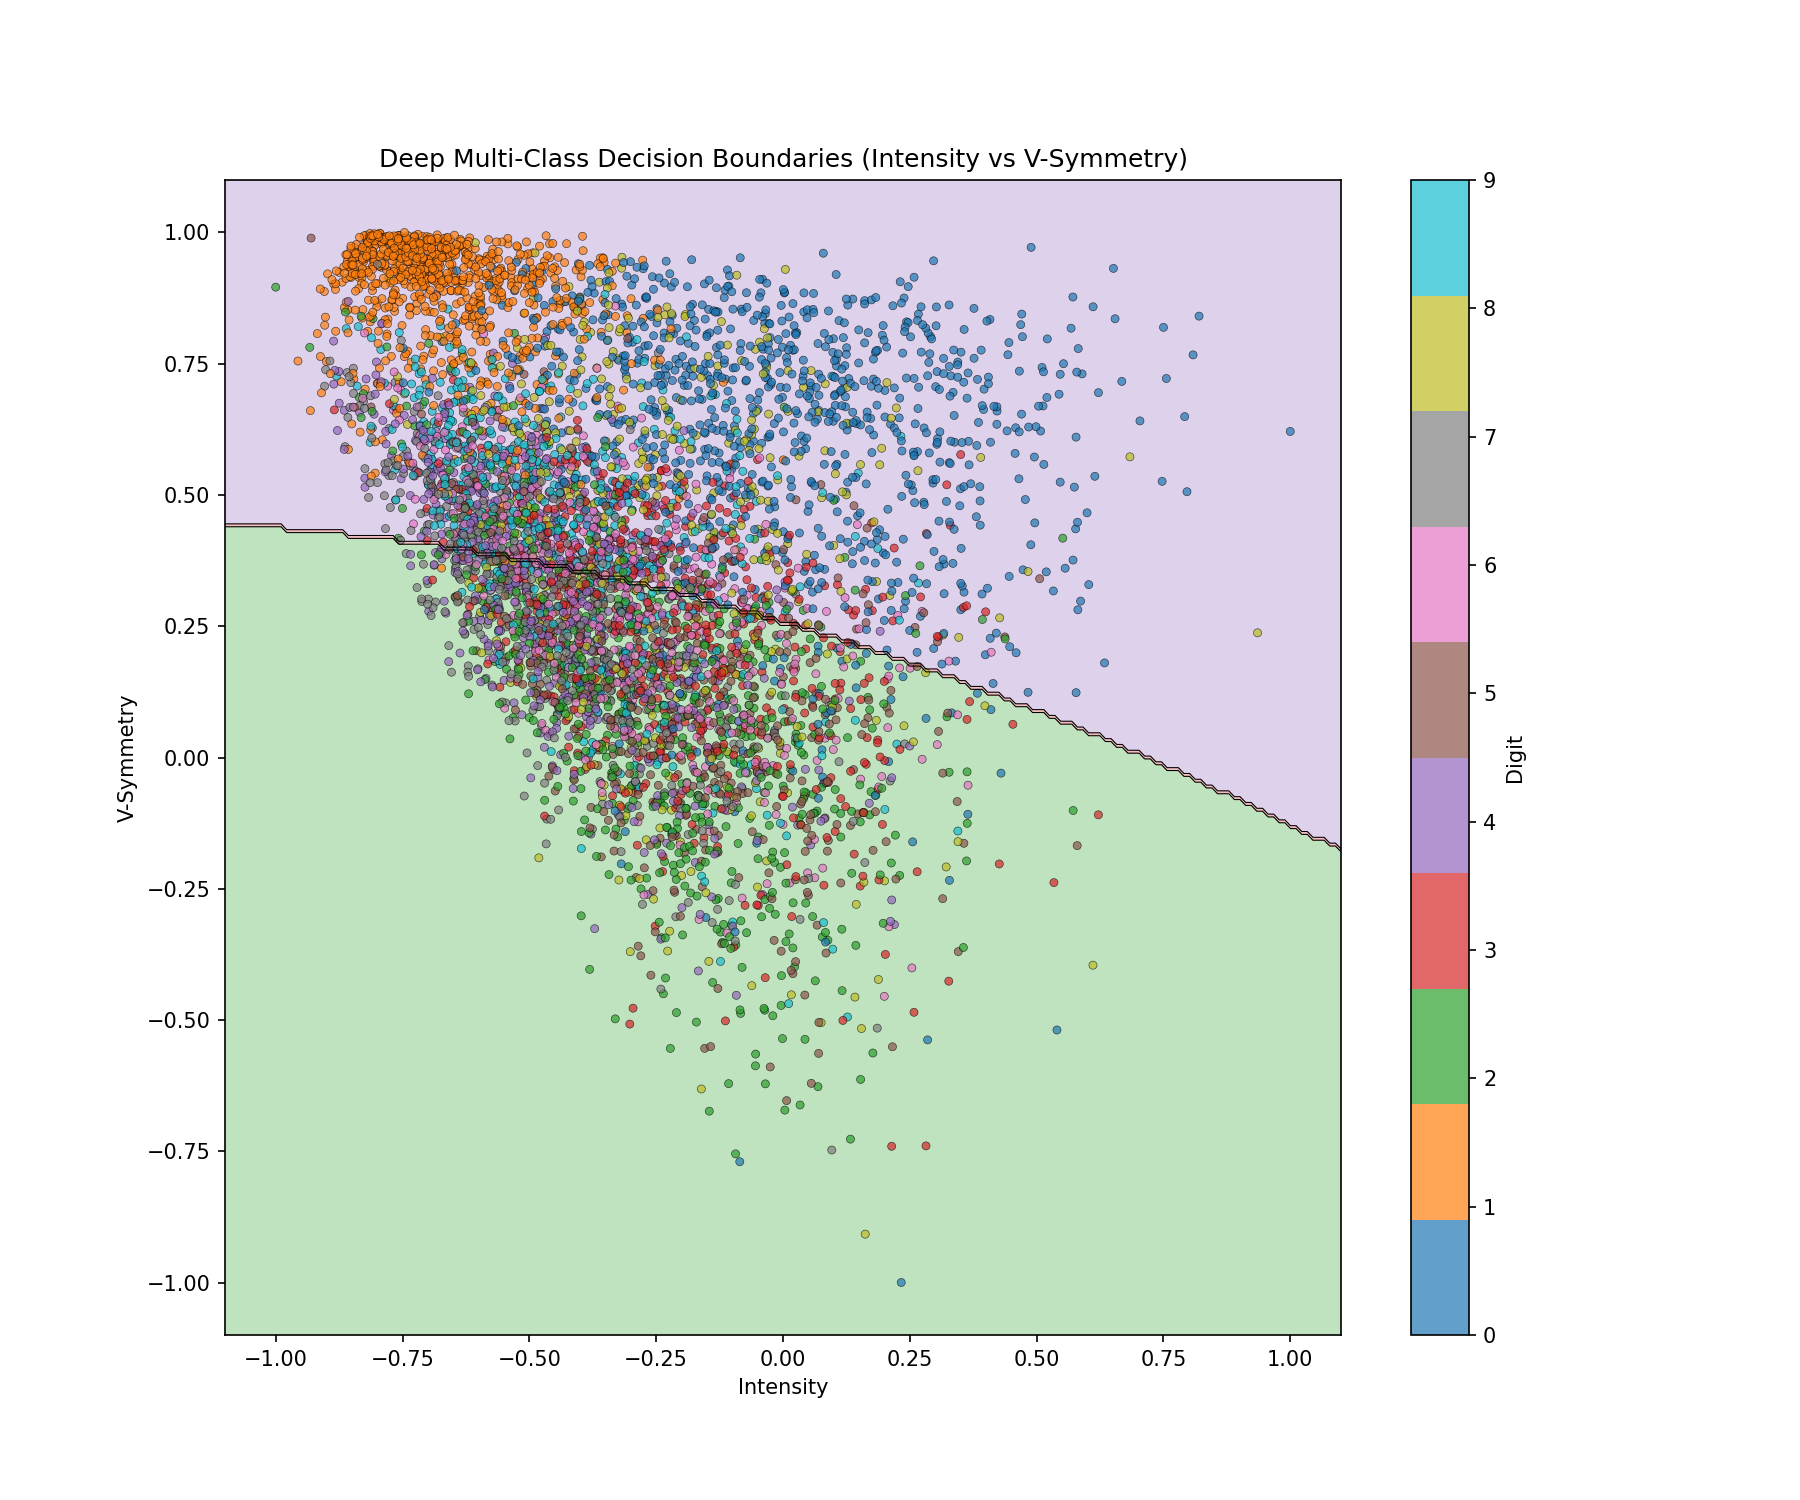
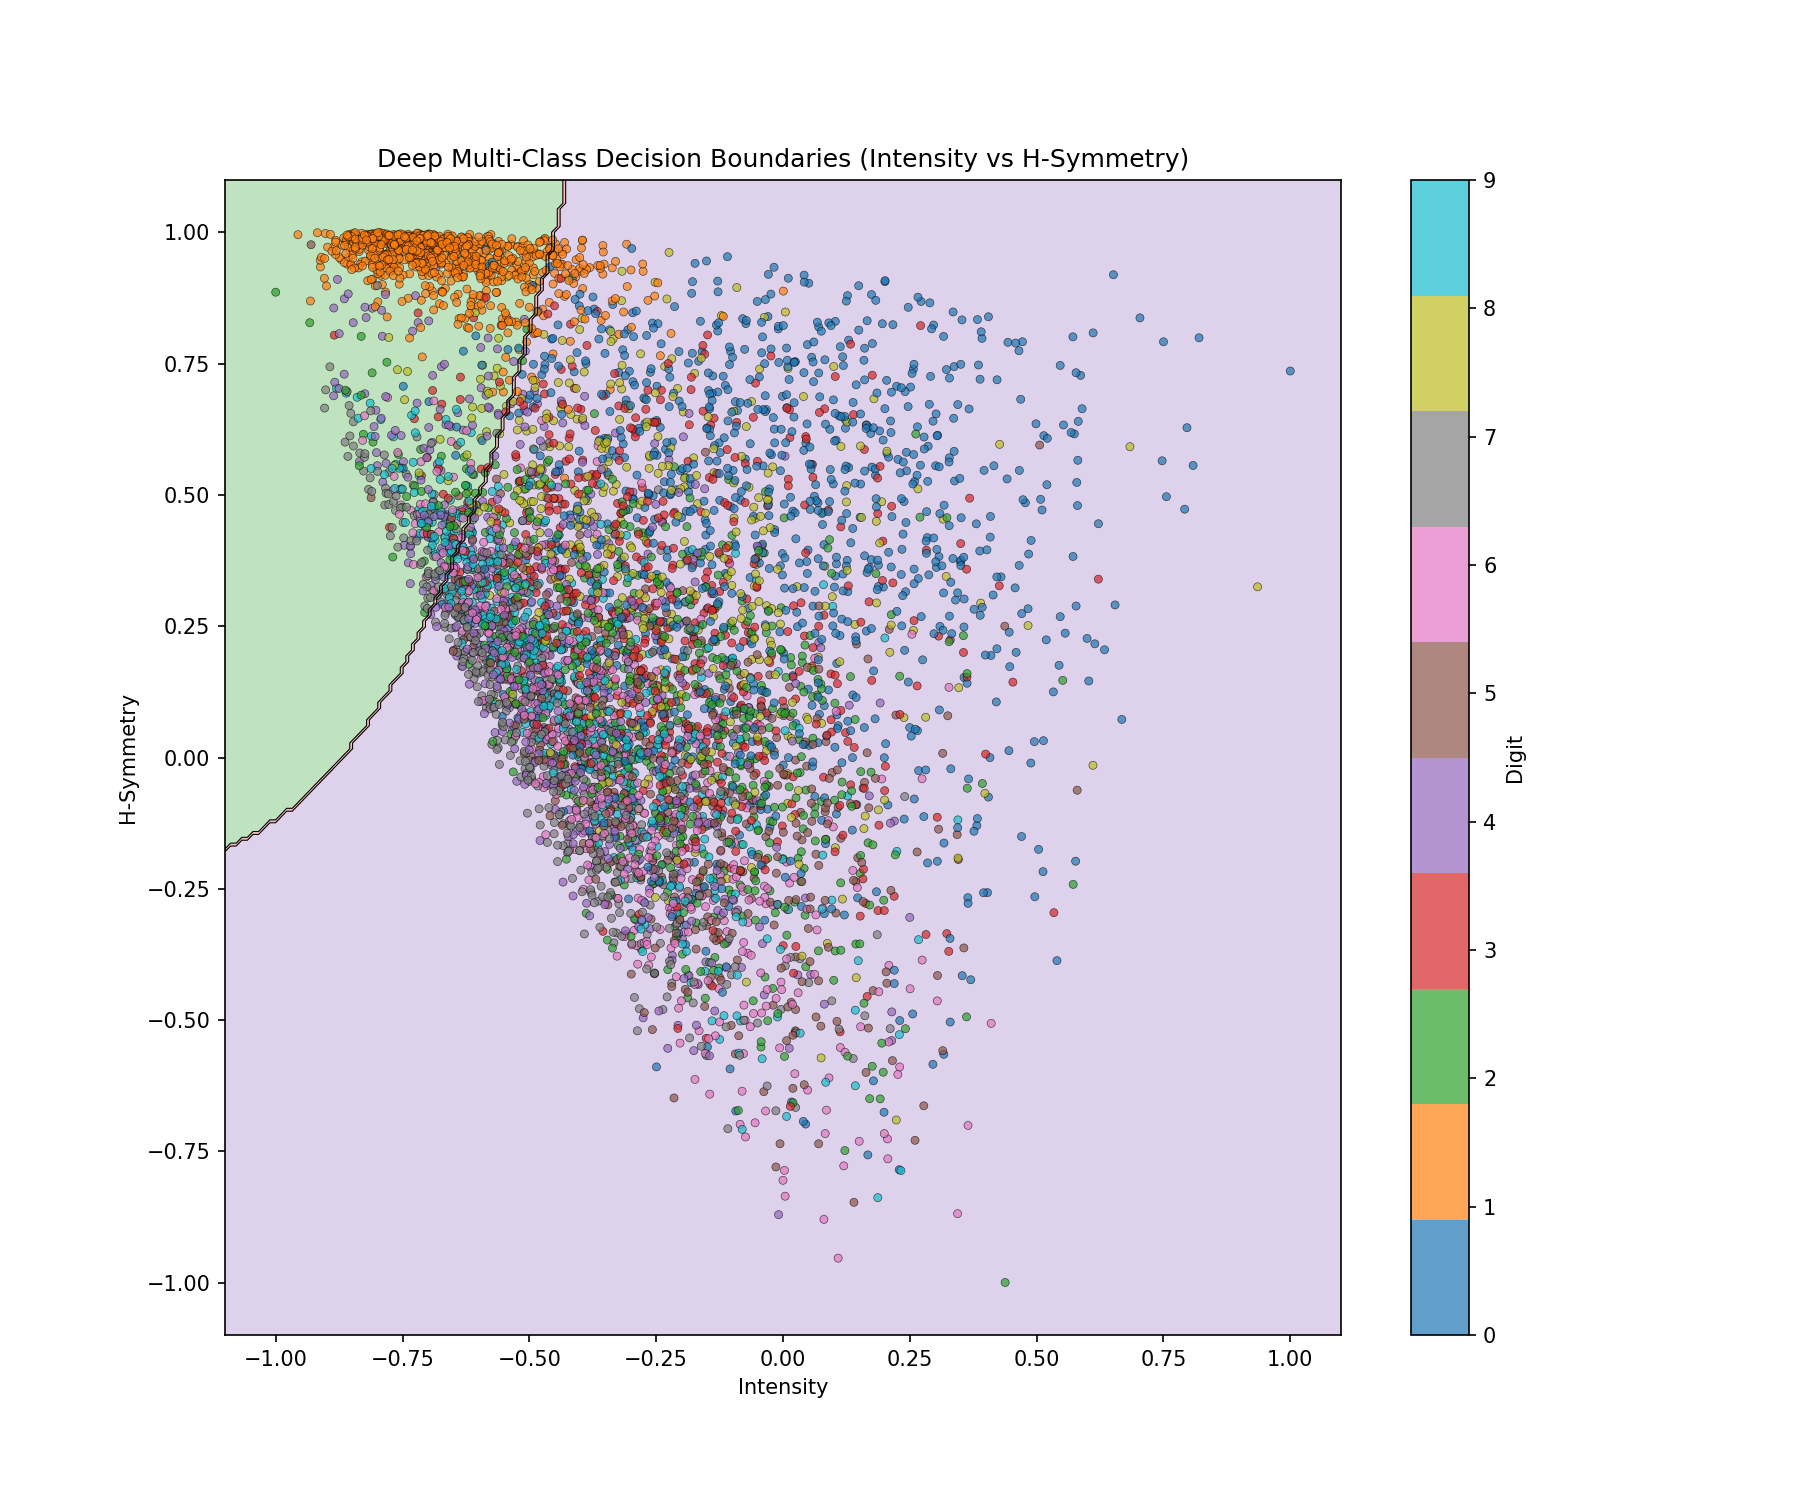
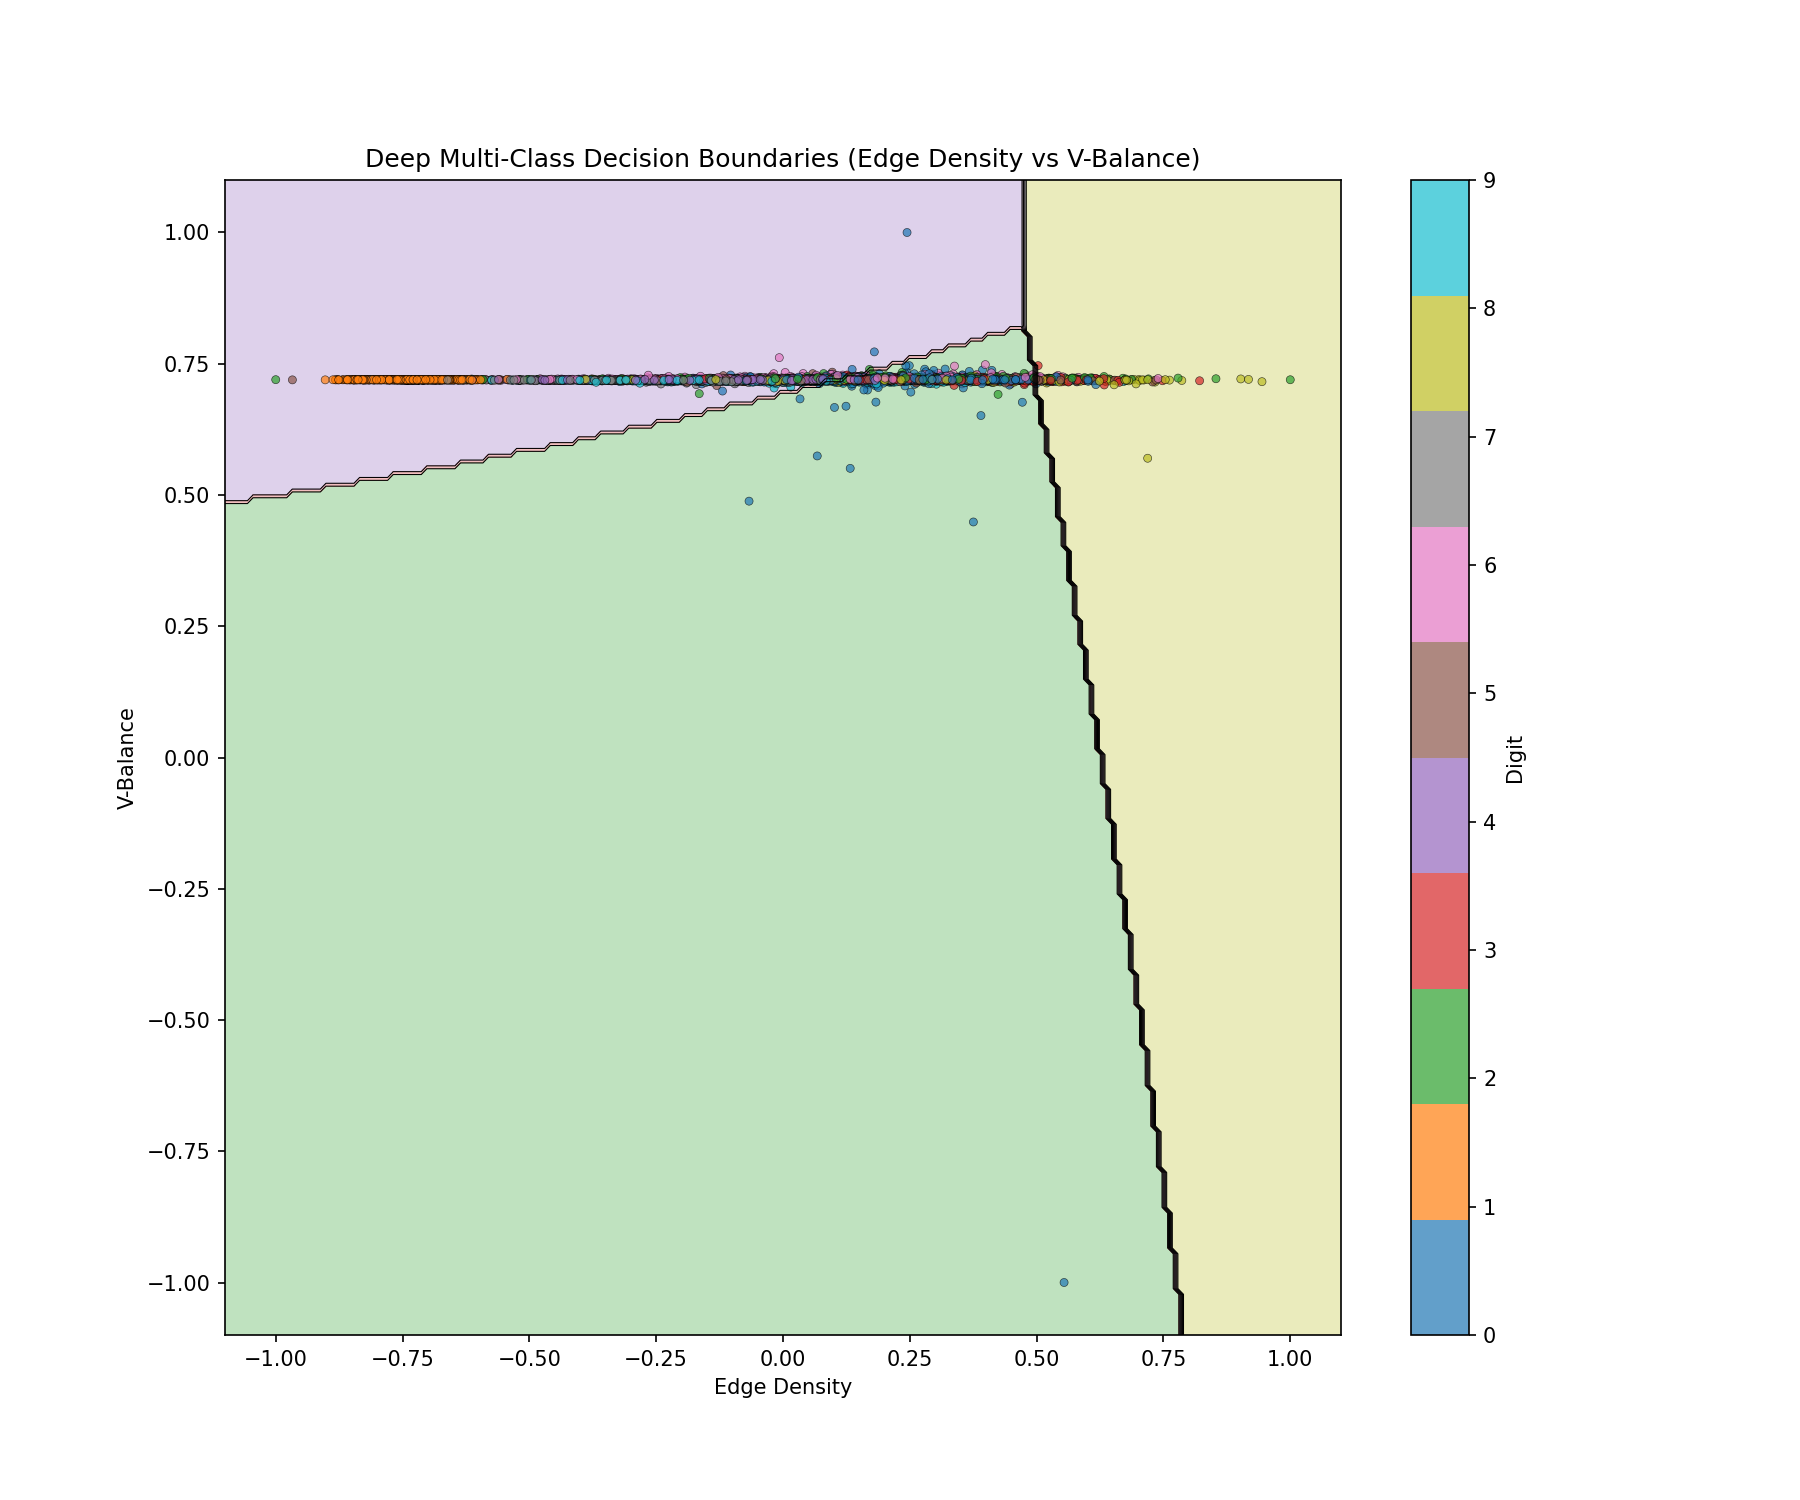
A neural network built entirely from scratch (no PyTorch or TensorFlow), extending an RPI machine learning course assignment. Hand-implements backpropagation, SGD, and one-vs-all classification over 284 engineered features. Achieves 94.5% accuracy on the USPS ZIP Digits dataset and 83% on my own handwritten samples.
Intensity vs. vertical symmetryIntensity vs. horizontal symmetryIntensity vs. edge balance
An intelligent music-playlist generator and player that uses LLMs and Spotify's API to curate, order, and enhance playlists based on vibe and metadata. Fine-tunes Qwen3-235B-A22B-Thinking on Hugging Face-hosted datasets built from Spotify audio analysis, and evaluates model choices with scikit-learn accuracy metrics.
PythonHugging FaceFine-TuningSpotify Web APIpandasscikit-learn
Graph Neural Networks for Material Property Prediction
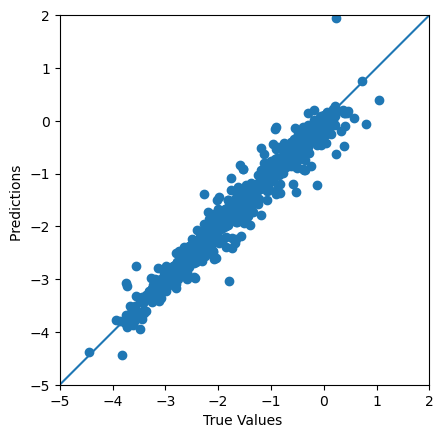
Research code from RPI's DMREF ("Designing Materials to Revolutionize and Engineer our Future") project, applying deep learning — autoencoders and graph neural networks — to material properties for aircraft-engine components under extreme conditions. Full write-up on the ML Engineer, Autoencoder Research entry.
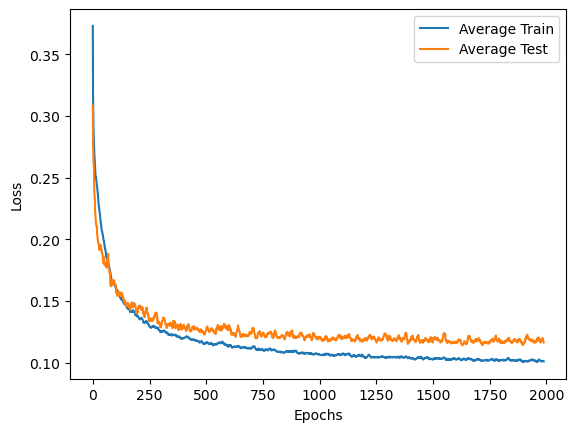
Predicted vs. true material property values for the GCN model on the Materials Project dataset: the R² = 0.971 result, straight from the research notebooks.Average train/test loss across 5-fold cross-validation for the GCN model, from the research notebooks.